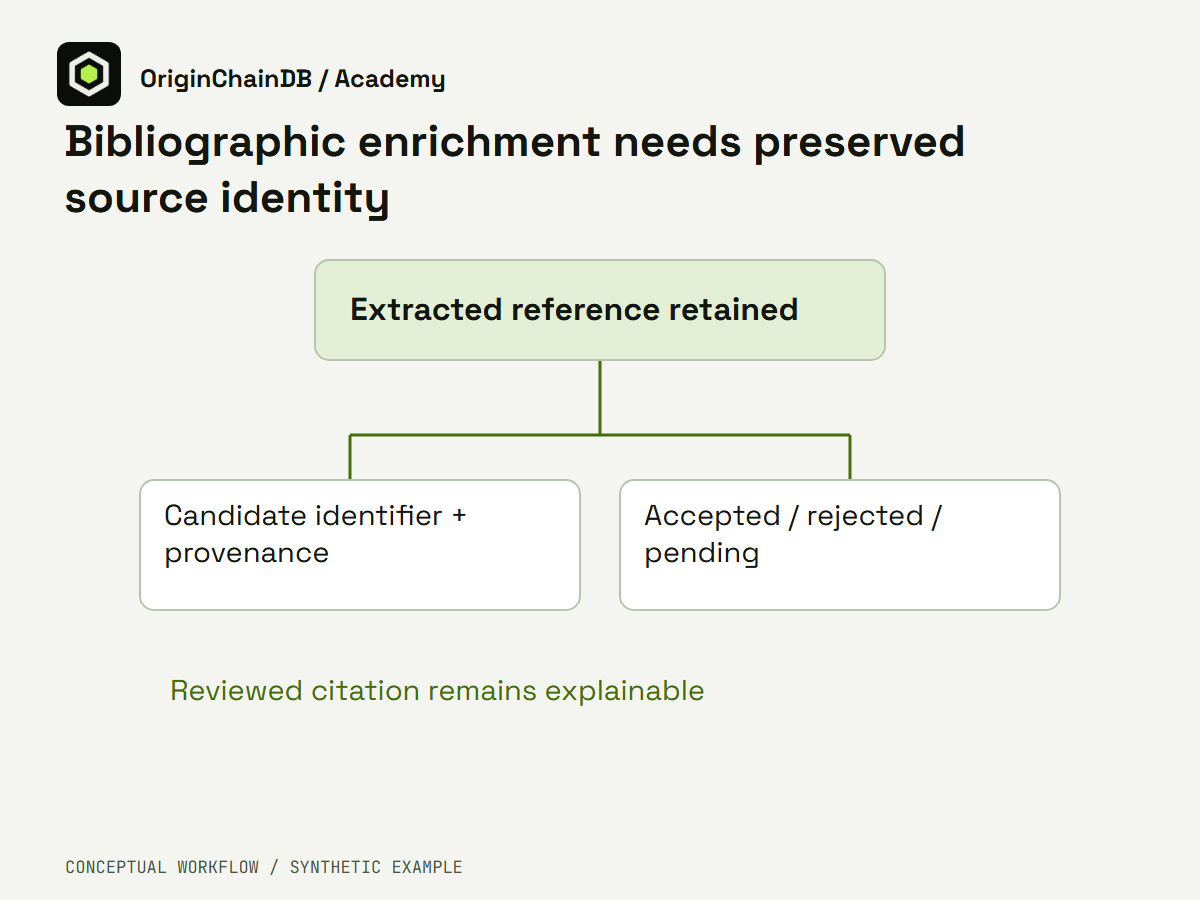
A citation-enrichment pipeline should preserve the original extracted reference and the evidence behind a proposed identifier. Treat a candidate match as a reviewable assertion until the application has enough evidence to accept it.
Executed synthetic walkthrough: this article includes actual light-mode OriginChainDB screenshots, the downloaded query CSV and a validated local application adapter. External industry systems were not connected.
Conceptual illustration of the synthetic application workflow. Light PNG · Dark PNG. This is not a product screenshot.
The sourced development
Crossref’s 6 October article describes how Grobid extracts bibliographic information from scholarly PDFs and uses Crossref metadata to enrich it. That workflow highlights an important integration boundary: extraction, enrichment and validation are separate activities. Our proposed OriginChainDB model below is an original application pattern, not an announced Crossref or Grobid integration.
Read the primary source. Crossref published the article on 6 October 2026.
The operational question
A title can be abbreviated, a reference can omit a field, and an extracted string can contain layout artifacts. Replacing the original with the first candidate identifier makes later review difficult. The application should answer which evidence produced a candidate and whether the candidate was accepted, rejected or left unresolved.
A tested OriginChainDB application pattern
Use source_document, extracted_reference, candidate_match and review_decision records. Retain source position, extractor version and metadata retrieval time. The synthetic example uses application IDs D1–D3 and candidate IDs C1–C3; it invents no real DOI or publication.
-
Create separate candidate and decision tables in a fresh demonstration schema. Preserve the synthetic raw reference and source label alongside each candidate instead of replacing them with an accepted identifier.
-
Inspect the three stored candidates and run the packaged LEFT JOIN report. Explicit decisions mark C1 accepted and C2 rejected; the missing decision for C3 remains pending_review.
-
Export the successful result as CSV and run route-export.py. It verifies the report state against the decision field and requires source evidence before emitting an application record.
-
Route those records into accepted, rejected and pending review views. A production document extractor or metadata API remains a separate adapter; neither was called in this demonstration.
Run the local application rule
The following executable fixture uses synthetic records and no network connection. It verifies the stated application rule without substituting a local result for a live database demonstration.
Download example.py · Expected local output
python example.py

candidates=[{"id":"C1","document":"D1"},{"id":"C2","document":"D2"},{"id":"C3","document":"D3"}]
decisions={"C1":"accepted","C2":"rejected"}
result=[{**c,"state":decisions.get(c["id"],"pending_review")} for c in candidates]
assert [r["state"] for r in result] == ["accepted","rejected","pending_review"]
The actual console report and downloaded CSV route C1 to accepted, C2 to rejected and C3 to pending_review while retaining each source document, raw reference and source label. The local export adapter checked the state handling. This proves the synthetic database-to-application handoff; it does not establish that any scholarly match is correct.
The recorded integration walkthrough
The three stills below were extracted from actual native console recordings after private fields were blurred before encoding. They show the synthetic stored inputs, the successful operation and its returned result. Query timing visible in the console is one observation and is not a performance benchmark.
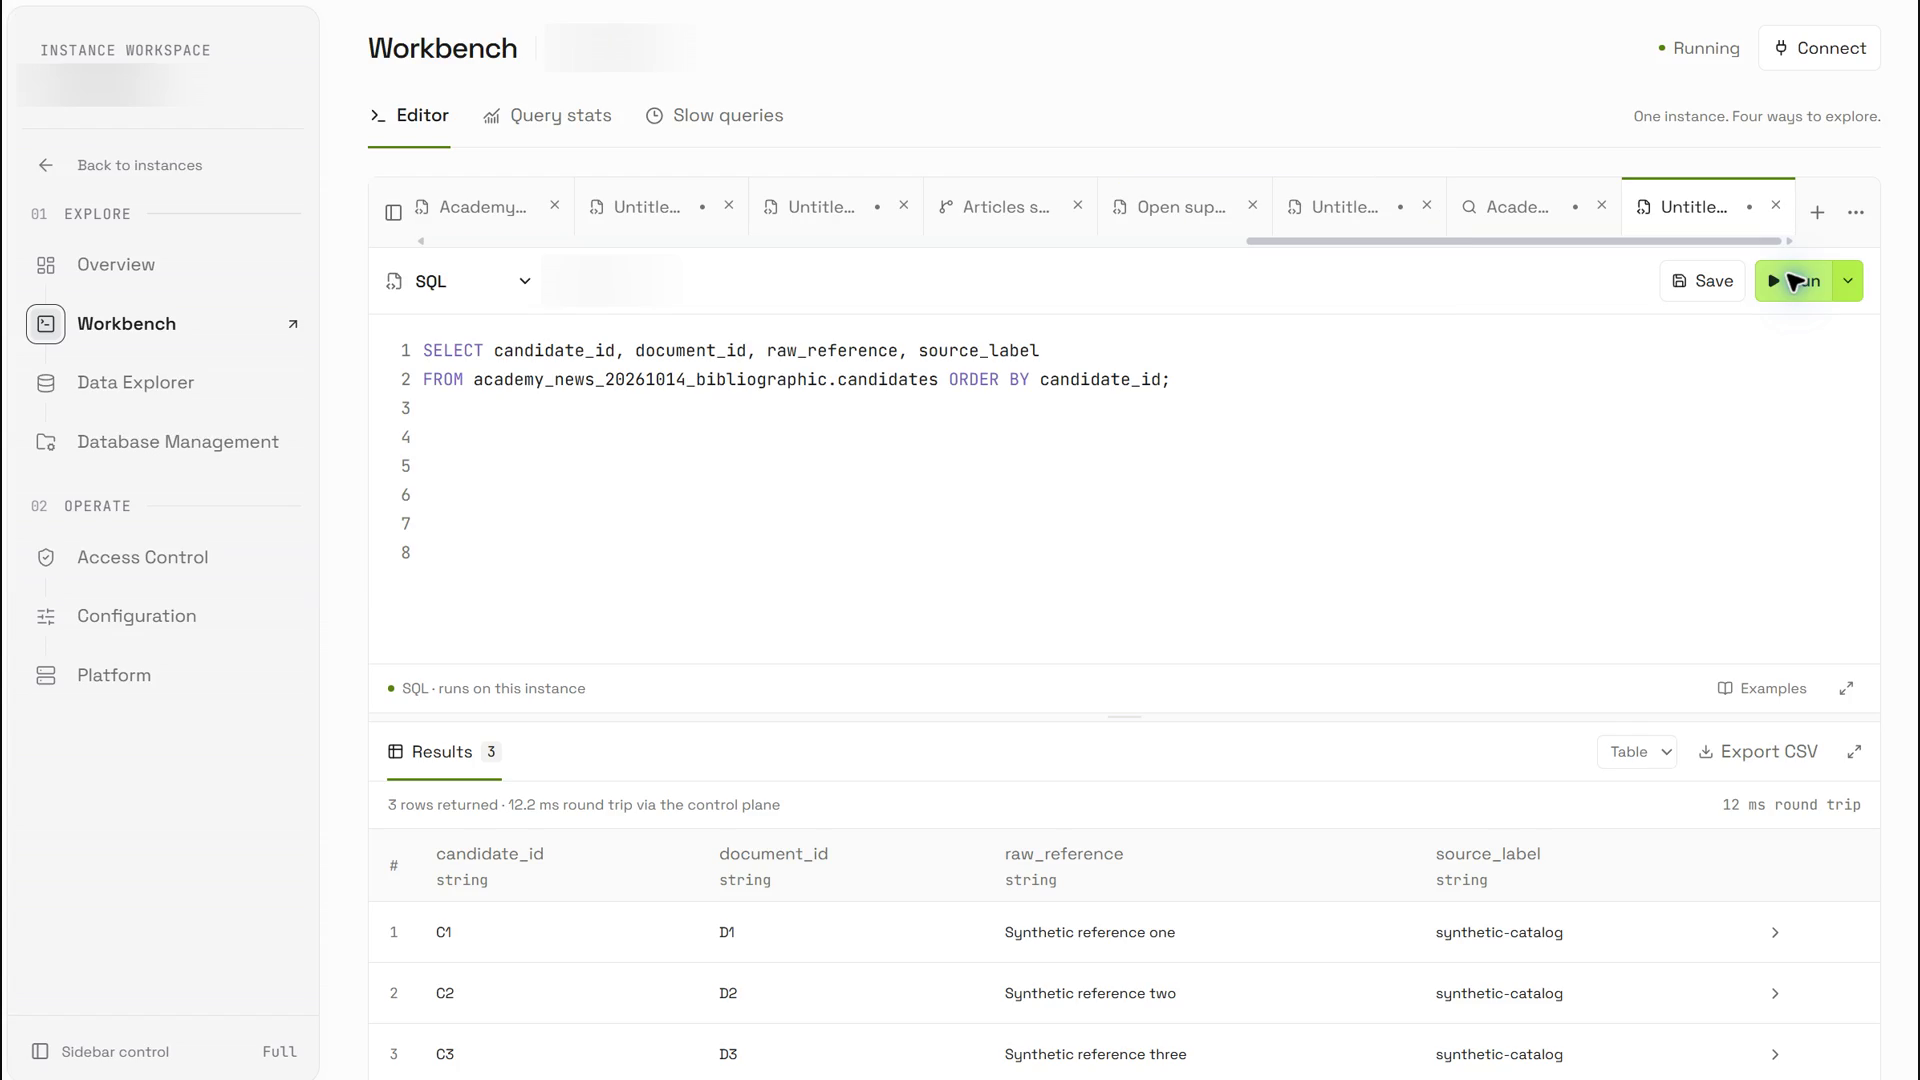
Three synthetic candidates retain source document, raw reference and catalog label. Open the image to inspect the full-size console view.
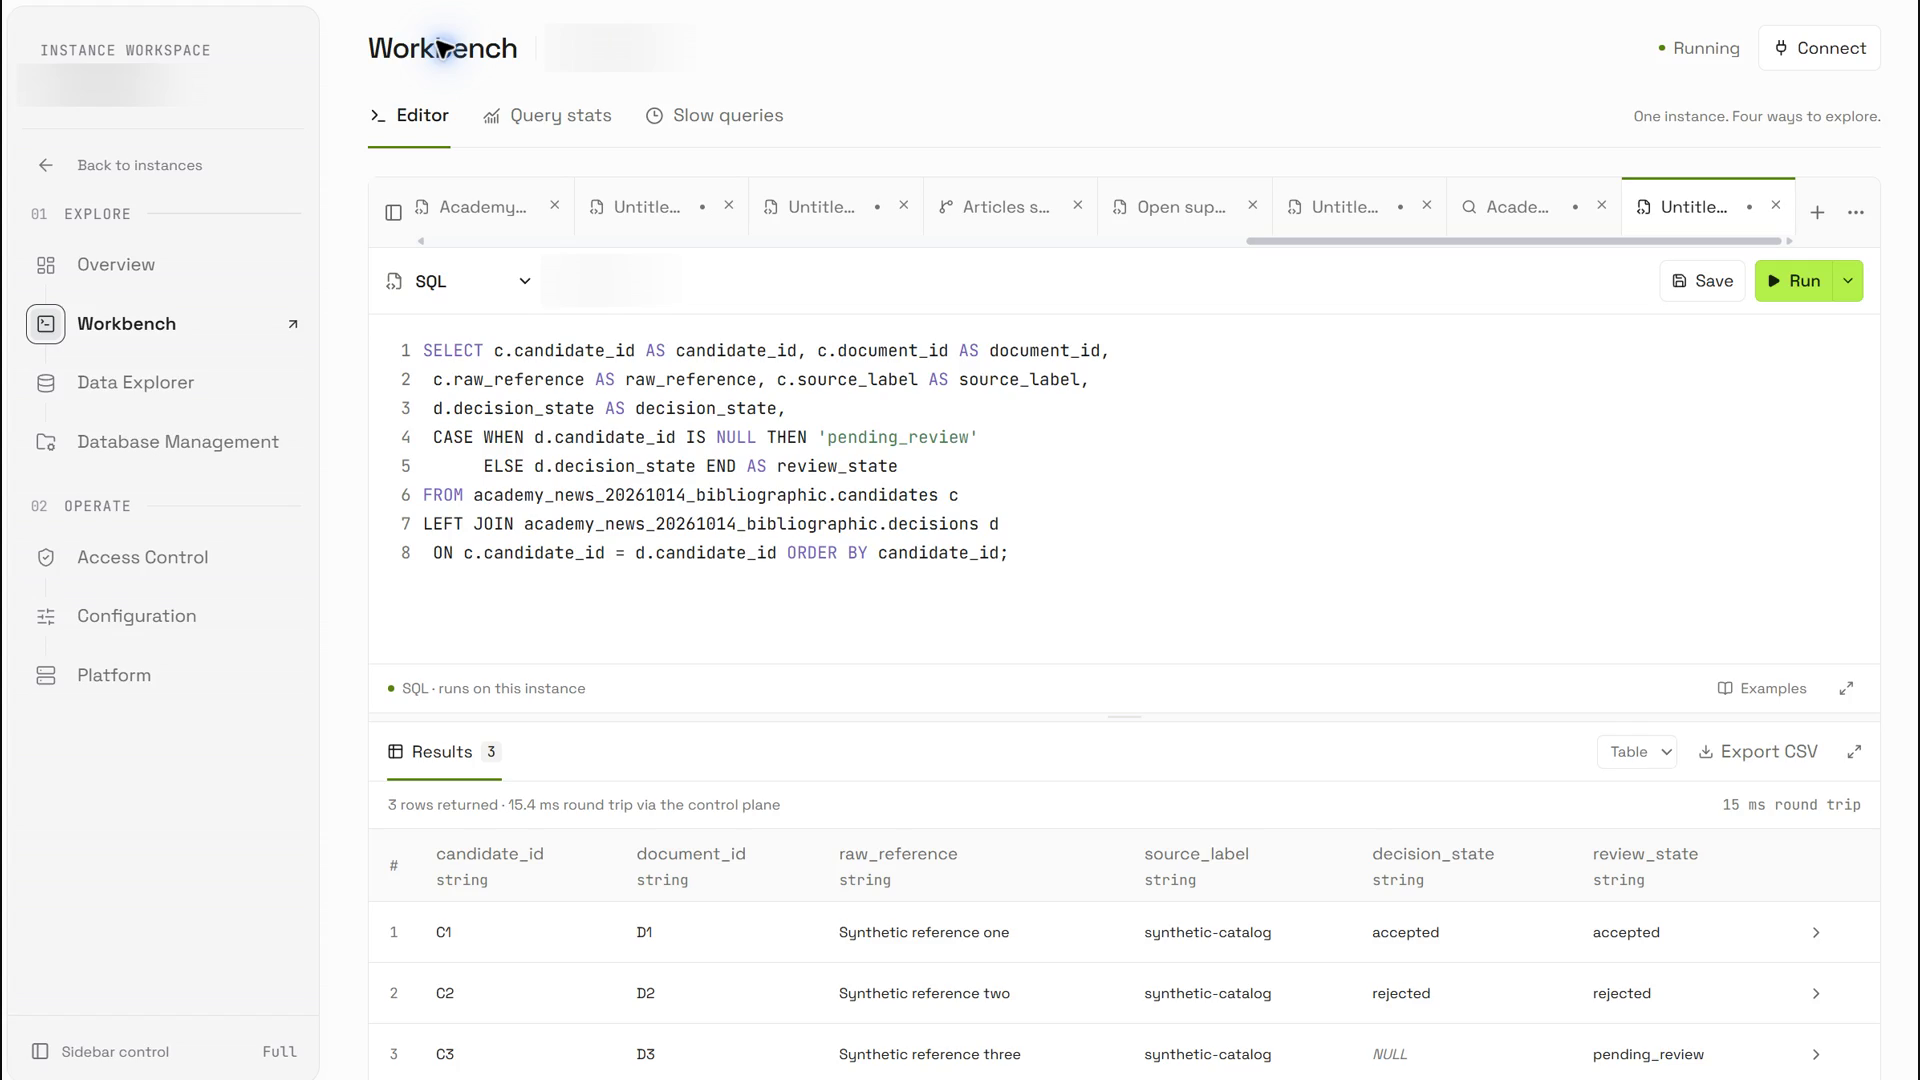
The LEFT JOIN operation keeps candidates with no review decision. Open the image to inspect the full-size console view.
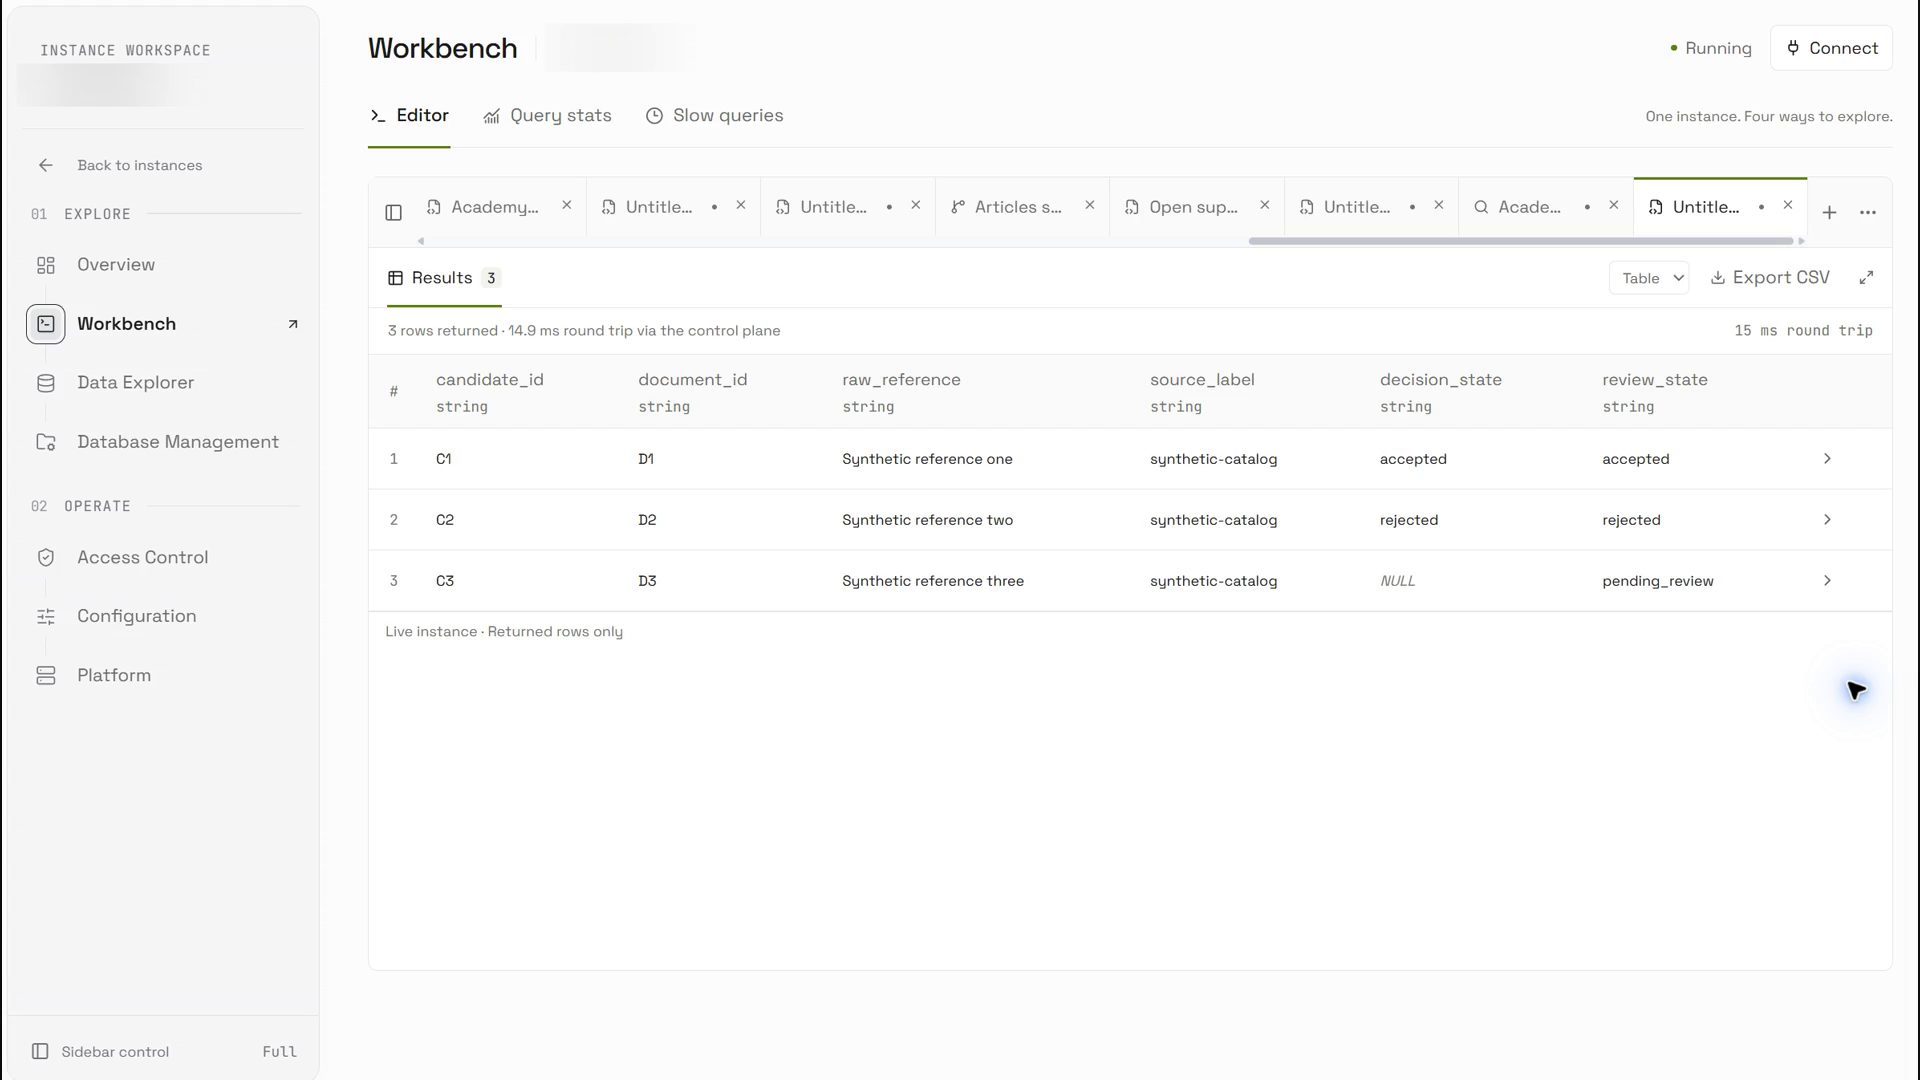
The actual result returns accepted, rejected and pending_review with source evidence intact. Open the image to inspect the full-size console view.
Reproduce the SQL-to-application handoff
Setup and report SQL · Actual downloaded CSV · CSV adapter · Executed adapter result · Verification receipt.
Use a new demonstration namespace for a repeat run; do not reset an existing one. Run the setup statements separately, inspect the input rows, then run the report below. Export the complete successful result and pass that file to the adapter.
SELECT c.candidate_id AS candidate_id, c.document_id AS document_id, c.raw_reference AS raw_reference, c.source_label AS source_label, d.decision_state AS decision_state, CASE WHEN d.candidate_id IS NULL THEN 'pending_review' ELSE d.decision_state END AS review_state FROM academy_news_20261014_bibliographic.candidates c LEFT JOIN academy_news_20261014_bibliographic.decisions d ON c.candidate_id = d.candidate_id ORDER BY candidate_id;python route-export.py export.csvThe adapter reads a local CSV, checks the application rule and emits records. It makes no network call and sends no external action. The synthetic contract CSV supplied beside the adapter is a separate offline test; it is not the live export.
Limits and evaluation
A bibliographic graph can preserve assertions but cannot make an inaccurate extraction true. Keep rate-limit handling, permitted API use, data licensing and source retention in the adapter’s contract. Avoid treating a similarity score or a returned identifier as independent verification.
The practical next step
Preserving the original reference creates an audit path when enrichment is uncertain. The recorded example shows how OriginChainDB can retrieve candidate evidence with unresolved decisions intact. Next, connect an authorized extraction and metadata adapter, preserve its versions and timestamps, and evaluate its candidate quality separately.
Claims and remaining evidence · Local execution receipt · OriginChainDB documentation. No partnership, native industry adapter, certification, customer outcome or production deployment is claimed.