
SQL · Find the facts
The question
Show critical alarms for these sites since the change.
Narrow events by region, time, device and severity.
Explore SQLTelecom
Connect alarms, network dependencies and recent changes. Help engineers find what affected sites share and retrieve the relevant runbook.
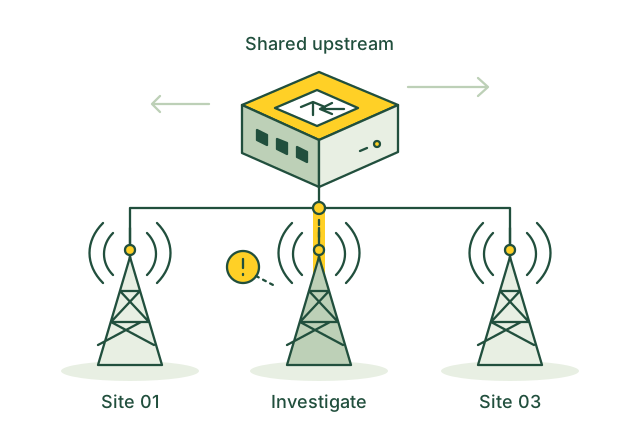
Trace affected sites to a shared network dependency.
Illustrative use case01 / Use case guide
Compare the data models behind everyday industry tasks, from finding records to following connections.
Suggested model combination
Scroll across to compare all four models| Use case | How the data models help | SQL | Vector | Graph | Full-text | Source |
|---|---|---|---|---|---|---|
| Prioritize active network alarms Engineers need a manageable list of current alarms to investigate. | SQL filters alarms by severity, site and time; Full-text finds specific alarm codes and messages. | SQL included | Vector not needed for this example | Graph not needed for this example | Full-text included | |
| Map affected customer services An incident team needs to know which services depend on failing equipment. | Graph follows equipment and service dependencies; SQL checks active services and current incident timestamps. | SQL included | Vector not needed for this example | Graph included | Full-text not needed for this example | |
| Compare recent maintenance changes Engineers need to see whether affected systems share a recent maintenance change. | Graph connects changes to affected equipment and services; SQL compares maintenance times with alarm onset for engineer review. | SQL included | Vector not needed for this example | Graph included | Full-text not needed for this example | |
| Find similar resolved incidents An engineer needs useful precedents for an unfamiliar network symptom. | Vector finds similar incident descriptions; SQL filters by equipment and resolution status; Full-text retrieves recorded fault codes and recovery notes. | SQL included | Vector included | Graph not needed for this example | Full-text included | |
| Track customer trouble tickets Support teams need the current state of a fault reported across partner systems. | SQL filters open tickets by severity and age; Graph follows related partner tickets; Full-text finds fault descriptions and ticket references. | SQL included | Vector not needed for this example | Graph included | Full-text included | |
| Check service order progress Operations staff need to find service orders that are still incomplete. | SQL filters orders by status and requested date; Graph connects each order to its service items for staff review. | SQL included | Vector not needed for this example | Graph included | Full-text not needed for this example | |
| Check address service availability A sales agent needs to know whether a requested service can be delivered. | Graph follows service designs to required resources; SQL checks location, capacity and qualification results before the service team confirms availability. | SQL included | Vector not needed for this example | Graph included | Full-text not needed for this example | |
| Find installation appointment slots A customer needs an available time for an installation or repair visit. | SQL filters open appointment slots by place and time; Graph links the visit to its order or trouble ticket. | SQL included | Vector not needed for this example | Graph included | Full-text not needed for this example | |
| Reconcile network inventory records Recorded equipment details no longer match the latest network discovery. | SQL compares discovered and recorded resource attributes; Graph traces changed equipment relationships for inventory staff to review. | SQL included | Vector not needed for this example | Graph included | Full-text not needed for this example | |
| Explain monthly bill changes A support agent needs to explain an increase in a customer's bill. | SQL compares charges, credits and discounts across billing periods; Graph connects each changed charge to its account and product. | SQL included | Vector not needed for this example | Graph included | Full-text not needed for this example |
Use the query interfaces you need, then connect their results through shared record IDs in your application.
These sources describe real industry workflows. The model combinations above are proposed OriginChainDB designs, not customer deployment claims.
02 / A closer look
Several sites report degraded service after a network change. Alarms arrive from different systems, customer reports use different descriptions, and the affected sites may share an upstream device. Engineers need evidence before choosing a recovery action.
Alarm volume hides related symptoms.
Service impact and physical dependencies live apart.
Old topology or runbooks can mislead an investigation.
Start with the affected sites and follow their upstream connections. Compare alarms with recent changes, then retrieve runbooks and previous incidents that help engineers test a cause.
03 / Queries
Select a model to see the question it answers.
The question
Narrow events by region, time, device and severity.
Explore SQLThe question
Find incidents and guidance with similar symptoms.
Explore VectorThe question
Trace service, site and upstream network dependencies.
Explore GraphThe question
Locate exact alarm codes and runbook instructions.
Explore Full-textUse shared record IDs to combine results from the different query interfaces in your application.
04 / Implementation
Use authorized read-only alarm exports, topology records and resolved incidents. Define the investigation questions with engineers.
Assign service, device and change IDs. Store event and ingestion times, topology validity and runbook versions. Refresh indexes after source changes.
Combine affected services, dependency paths and recent changes. Link supporting runbooks and mark uncertain relationships for the engineer to check.
Check missed dependencies and stale topology against known incidents. Pilot read-only triage first; keep network changes behind existing operator approvals.
05 / Testing
Compare these results with your current process before rollout.
Measure how quickly an engineer finds a relevant dependency and supporting records.
Check whether the known cause appears among the evidence in replayed incidents.
Track stale or incorrect links discovered during incident review.
06 / Sources
Published projects and reference material relevant to this use case.
KDDI
KDDI announced operation of a fault-recovery support agent for selected services. It connects system information, equipment alarms and operational history to help staff identify failure causes.
Read the sourceTelefónica
Telefónica discusses network incident resolution using correlated information across services, users and network elements, alongside operational systems and AI assistance.
Read the sourceThese are industry references, not OriginChainDB customer stories. The implementation above is a proposed example.
Build with OriginChainDB